
About EchoDrift
The Universal Atlas of Phonetic Evolution — an interactive map of how every human speech sound drifts, shifts, and mutates across languages and time.
Why This Exists (A Confession)
It started as an argument. Or rather, as mild exasperation at the kind of amateur etymology that goes: "Clearly, the English word bad and the Persian word bad (بد) are cognates — after all, [b] and [b] are the same sound!" Or its cousin: "[p] can shift to [f], and [f] can shift to [v], so obviously these two words are related."
The logic is seductive. And it's also how you end up "proving" that every word in every language is related to every other word. Technically, you can chain sound shifts together across enough centuries, languages, and intermediary steps to get almost anywhere. Which raises the question: how far does "anywhere" actually go?
The original goal was to fill a matrix — every IPA sound against every other IPA sound — and see which pairs have a documented phonetic transformation in at least one language, at some point in history. The working hypothesis was "Any-to-Any": that every sound can, in some language, become any other sound. (The repository is still named a2a, because the creator couldn't decide between "Any-to-Any" and "All-to-All" and asked an LLM — which promptly renamed it EchoDrift. So here we are.)
The hypothesis turned out to be nearly correct. As you can see below.
The Vowel Matrix: Almost Full
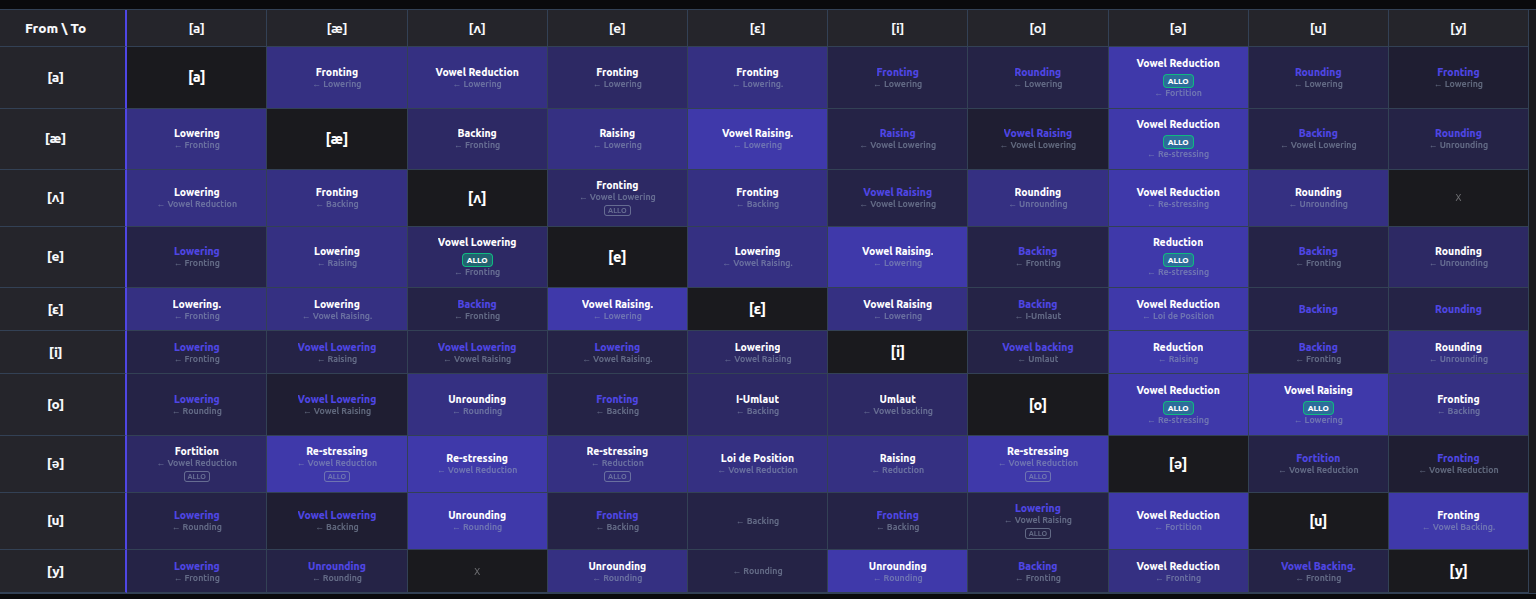
For vowels, the Any-to-Any hypothesis is essentially proven. Every vowel phoneme in the matrix has a documented phonetic shift to every other vowel — except one pair: [ʌ] and [y]. The unrounded central-low vowel (as in English strut) and the rounded front high vowel (as in French lune) have stubbornly refused to shift into each other in any documented language.
We dare you to find a language that has, or had, a [ʌ]→[y] or [y]→[ʌ] shift. If you do, please email us immediately.
What's in the Atlas
- 1,500+ documented phonetic transformations across consonants, vowels, diphthongs, and allophones
- 130+ language families — Germanic, Romance, Semitic, Sino-Tibetan, Austronesian, Niger-Congo, Mayan, and more
- Allophone documentation with ALLO badges distinguishing synchronic variants from diachronic shifts
- Commonality heatmap — cell color intensity reflects how frequently each shift occurs cross-linguistically (scale 1–5)
- Unattested cells marked with "X" — researched and confirmed absent, not just missing
- Inverse detection — if A→B is documented, the B→A cell automatically links back
- Matrix modes — Symmetric, Vowel-to-Consonant (v2c), and Consonant-to-Vowel (c2v) views for complex cross-category shifts
- Deep-linkable URLs — every transformation has a unique, citable address (e.g.
/transform/p/f)
A Quick Primer: Shifts, Drifts, and Allophones
Phonetic shifts (also called sound changes or phonemic shifts) are systematic changes in pronunciation that affect all speakers of a language over time. They follow rules — never random, always conditioned by phonetic environment, neighboring sounds, or social pressure. Grimm's Law, for instance, describes how Proto-Indo-European [p, t, k] shifted to Germanic [f, θ, h] — explaining why Latin pater corresponds to English father.
Phonetic drift is the gradual, cumulative direction of these changes across generations — the slow continental drift of a language's sound system. English vowels drifted dramatically during the Great Vowel Shift (1400–1700), turning Middle English mees [meːs] into modern mice [maɪs].
Allophones are a different beast: not historical changes, but synchronic variants — pronunciations of the same phoneme that differ depending on context, without changing meaning. English speakers pronounce the [t] in top aspirated ([tʰ]) and the [t] in stop plain ([t]), without noticing. EchoDrift documents both types, with allophone cells clearly marked with an ALLO badge.
Methodology
Every documented phonetic transformation in this atlas is backed by academic sources: peer-reviewed research, established historical sound laws, or systematic dialectal observations. The research process includes:
- LLM-Assisted Research: Language models systematically search for academic sources on each phonetic shift across diverse language families, covering obscure dialects and under-documented languages.
- Cross-Verification: Each shift is verified using independent sources. Shifts that appear only in AI-generated text without traceable academic backing are rejected.
- Multilingual Documentation: Examples are drawn from multiple language families with transcriptions standardized to IPA, and original scripts preserved.
- Source Databases: Google Scholar, Google Books, CyberLeninka, JSTOR, and specialized linguistic databases.
- Unattested Cells: Pairs marked with an "X" have been researched and determined to lack any documented regular shift — distinguishing them from cells that simply haven't been researched yet.
Data Model
EchoDrift uses a GitHub-as-Database architecture. Each cell in the matrix is a standalone JSON file containing:
- Preamble: A concise linguistic explanation of the shift and its phonetic motivation.
- Phonetic Effects: Standardized process tags (Lenition, Fortition, Palatalization, Assimilation, Vowel Raising, Vowel Reduction, etc.).
- Language Examples: Documented cases from multiple language families, with native scripts alongside IPA transcriptions.
- Scholarly Citations: Direct links to peer-reviewed sources, historical references, and academic databases.
- Metadata: Certainty and commonality ratings (1–5), language family tags, allophone markers, and links to related transformations.
Contribute
The atlas is a living document. If you find a missing transformation, a better academic source, or — please — a language with a [ʌ]→[y] shift, reach out at [email protected] or contribute directly via our GitHub Repository (formerly PhonoMorph). Click any empty cell in the matrix to get started.